

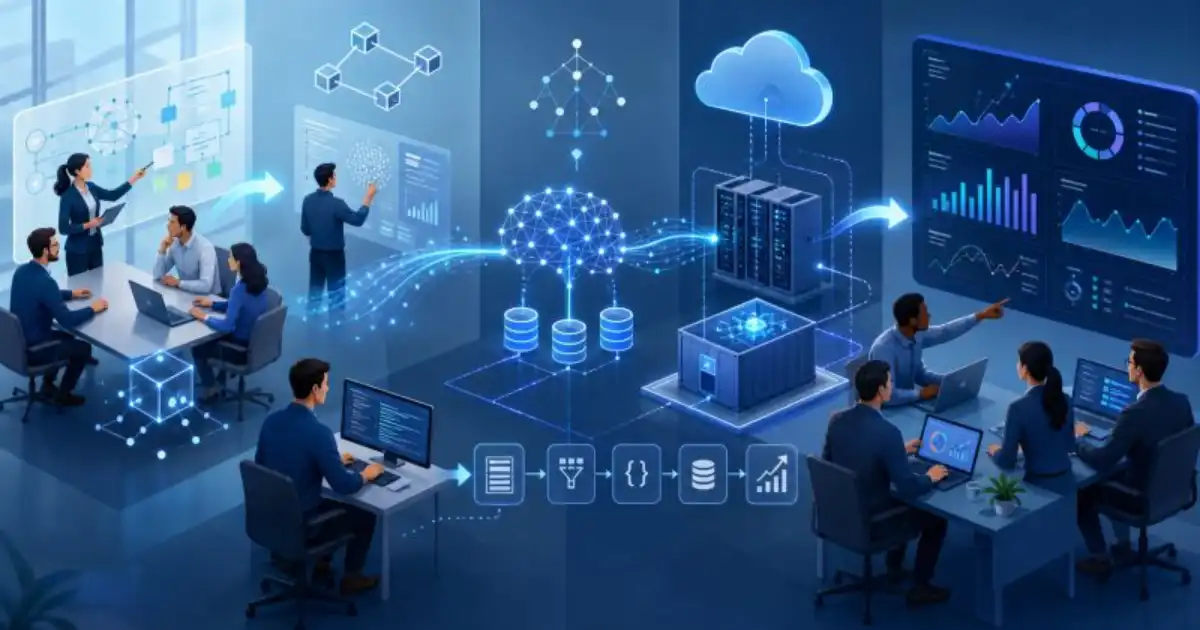
People talk about models, prompt engineering, agents, and the latest breakthroughs. But behind every successful AI system sits an enormous amount of infrastructure.
Models do not train themselves. GPUs do not magically appear. Data pipelines do not maintain themselves. Production inference does not scale automatically.
This is where AI infrastructure comes in.
One reason many people struggle to understand the field is that AI infrastructure sits at the intersection of several disciplines. It borrows concepts from cloud engineering, DevOps, platform engineering, distributed systems, MLOps, and data engineering.
When I first started working around production AI systems, what surprised me most was how little of the job involved building models. Most of the work involved making those models reliable, scalable, secure, and cost-effective.
If you’re wondering How Does AI Infrastructure Learning Path Work, the answer is simpler than most people think. You do not start with GPUs and large language models. You start with infrastructure fundamentals and gradually build toward AI-specific systems.
What Is AI Infrastructure Really?
The Simple Definition
AI infrastructure is the collection of systems, tools, platforms, and processes that allow AI models to be trained, deployed, monitored, and scaled in production.
Think of it as the operating environment for AI.
If a machine learning model is the engine, AI infrastructure is everything around it:
- Compute resources
- Storage systems
- Networking
- Containers
- Kubernetes clusters
- Data pipelines
- Model deployment platforms
- Monitoring systems
- GPU infrastructure
Without infrastructure, the model is just a file sitting on disk.
Why AI Infrastructure Exists
Training a model on a laptop is relatively easy.
Running that same model for thousands or millions of users is an entirely different challenge.
For example, imagine a customer support chatbot serving 50,000 users daily.
You need:
- GPU resources
- Load balancing
- Request routing
- Model versioning
- Monitoring
- Logging
- Security controls
- Disaster recovery
AI infrastructure exists because real-world AI systems must operate continuously under production conditions.
Why Traditional Infrastructure Is Not Enough
Traditional applications mostly process business logic.
AI workloads introduce new challenges:
- Massive datasets
- GPU scheduling
- Model artifact management
- Distributed training
- Inference optimization
- Feature pipelines
A web server and a database are no longer enough.
Once machine learning enters the picture, infrastructure complexity increases quickly.
What Does an AI Infrastructure Engineer Actually Do?
Daily Responsibilities
The role varies by company, but common responsibilities include:
- Building AI deployment platforms
- Managing Kubernetes clusters
- Supporting GPU workloads
- Creating CI/CD pipelines
- Automating infrastructure provisioning
- Monitoring AI systems
- Improving model serving performance
- Managing cloud resources
A typical day often involves troubleshooting rather than building.
One mistake people make is assuming the job revolves around AI models. In reality, much of the work involves reliability engineering.
Where This Role Fits in an AI Team
AI infrastructure engineers typically sit between several groups:
- Data scientists
- ML engineers
- Platform engineers
- DevOps teams
- Security teams
Their job is to create the environment where AI practitioners can work efficiently.
If ML engineers build models, AI infrastructure engineers build the roads those models travel on.
Skills That Matter Most
The strongest AI infrastructure engineer skills are usually:
- Linux administration
- Cloud platforms
- Kubernetes
- Python
- Networking
- Infrastructure as Code
- Monitoring and observability
- Distributed systems thinking
Notice what is missing.
Advanced machine learning theory.
Understanding ML is useful, but infrastructure expertise usually creates more value in this role.
How Does AI Infrastructure Learning Path Work?
The learning path follows a layered approach.
Each stage depends on the one before it.
- Linux, networking, and Python
- Cloud infrastructure
- Containers and Kubernetes
- Data engineering and MLOps
- GPU infrastructure
- LLMOps and AI serving
- Platform engineering
Many beginners try to skip directly to LLMs.
That is usually a mistake.
Every advanced AI platform ultimately rests on infrastructure fundamentals.
The best AI infrastructure engineer roadmap is built from the bottom up.
Stage 1: Learn Linux, Networking, and Python
Why Linux Matters
Most AI infrastructure runs on Linux.
Cloud servers run Linux.
Kubernetes nodes run Linux.
GPU clusters run Linux.
Learn:
- Shell commands
- File systems
- Permissions
- Process management
- System services
- Resource monitoring
Comfort with Linux pays dividends throughout your entire career.
Networking Skills Most Beginners Ignore
Networking is probably the most overlooked skill in AI infrastructure.
Yet many production failures involve networking.
Learn:
- TCP/IP
- DNS
- HTTP/HTTPS
- Load balancing
- Reverse proxies
- Firewalls
When a model endpoint becomes unreachable, networking knowledge often solves the problem faster than AI knowledge.
Python for Automation
You do not need to become a software engineer.
You do need enough Python to automate tasks.
Focus on:
- APIs
- Automation scripts
- Data processing
- Cloud SDKs
- Infrastructure tooling
Most infrastructure teams use Python daily.
Stage 2: Learn Cloud Infrastructure
AWS, Azure, or Google Cloud?
The truth is that cloud concepts matter more than the provider.
Pick one platform.
Learn it thoroughly.
AWS remains the most common starting point, but Azure and Google Cloud are equally valid choices.
The first cloud platform teaches the concepts.
The second becomes much easier.
Services Worth Learning First
Start with:
- Virtual machines
- Object storage
- Managed databases
- IAM
- Virtual networks
- Monitoring services
Avoid trying to learn every service.
Most engineers use a relatively small subset repeatedly.
Common Beginner Mistakes
I see three mistakes frequently:
First, collecting certifications without building projects.
Second, learning services instead of architectures.
Third, ignoring cost management.
In production environments, infrastructure cost often becomes a major engineering concern.
Stage 3: Learn Docker and Kubernetes
Why Containers Changed Everything
Containers solved a huge deployment problem.
Instead of saying “it works on my machine,” teams package applications into portable environments.
Docker became the standard approach.
For AI systems, containers simplify:
- Model deployment
- Environment consistency
- Dependency management
- Scaling
Kubernetes Without the Hype
Kubernetes gets surrounded by hype.
The reality is simpler.
Kubernetes is a scheduling and orchestration system.
It helps manage large numbers of containers.
That is its core purpose.
Everything else builds on top of that idea.
What You Actually Need to Learn
Focus on:
- Pods
- Deployments
- Services
- Ingress
- Persistent storage
- Autoscaling
- Namespaces
Do not memorize every Kubernetes feature.
Learn how applications run inside clusters.
That understanding matters far more.
Stage 4: Learn Data Engineering and MLOps
Why Data Pipelines Matter
Models depend on data.
Bad pipelines create bad models.
Simple as that.
Many AI failures originate from data quality problems rather than model issues.
Understanding data movement is critical.
What MLOps Really Means
The MLOps learning path is often presented as a collection of tools.
That misses the point.
MLOps is operational discipline for machine learning.
It includes:
- Reproducibility
- Automation
- Deployment
- Monitoring
- Governance
Think of it as DevOps adapted for ML systems.
Tools Worth Knowing
Useful tools include:
- Airflow
- MLflow
- Kubeflow
- Prefect
- Argo Workflows
- Feast
Do not obsess over specific tools.
Focus on the problems they solve.
Tools change. Principles last longer.
Stage 5: Learn GPU Infrastructure and AI Systems
Why GPUs Matter
Modern AI workloads rely heavily on GPUs.
Training large models on CPUs would be painfully slow.
GPU infrastructure introduces new operational challenges:
- Resource scheduling
- Driver management
- Cluster utilization
- Cost optimization
This is where many traditional infrastructure engineers begin entering AI-specific territory.
Distributed Training Basics
Eventually, one GPU is not enough.
Training workloads become distributed.
Important concepts include:
- Data parallelism
- Model parallelism
- Checkpointing
- Distributed storage
- Cluster networking
You do not need deep mathematical expertise.
You do need to understand how workloads scale across multiple machines.
What Most New Learners Overlook
Most people focus on raw GPU power.
The real bottleneck is often elsewhere.
Storage systems.
Networking throughput.
Data loading performance.
In production AI environments, GPUs are only one piece of the puzzle.
Stage 6: Learn LLM Infrastructure and LLMOps
Model Serving
Training gets attention.
Inference pays the bills.
Model serving involves making models available through APIs and applications.
Key concerns include:
- Latency
- Throughput
- Availability
- Cost
A fast model with poor infrastructure still creates a bad user experience.
Vector Databases
Many LLM applications use vector databases to store embeddings.
Popular options include:
- Pinecone
- Weaviate
- Milvus
- Qdrant
Their purpose is straightforward.
They help retrieve semantically relevant information quickly.
RAG Systems
Retrieval-Augmented Generation (RAG) combines retrieval and generation.
Instead of relying solely on model knowledge, the system fetches relevant information before generating a response.
This has become one of the most practical production AI architectures.
Most modern LLMOps roadmap discussions include RAG because companies want current and domain-specific answers.
Inference Optimization
Inference costs can become enormous.
Optimization techniques include:
- Quantization
- Caching
- Batching
- Model compression
- GPU utilization tuning
This is where infrastructure decisions directly affect business outcomes.
Stage 7: Learn AI Platform Engineering
What Platform Engineering Means
Platform engineering focuses on building internal platforms that make developers and ML engineers more productive.
Instead of manually configuring infrastructure, teams use self-service platforms.
Think of it as creating products for internal engineering teams.
Why Companies Are Investing in It
AI adoption creates operational complexity.
Organizations want:
- Faster deployments
- Standardized workflows
- Better governance
- Lower operational overhead
Platform engineering addresses these challenges at scale.
Future Career Opportunities
The AI platform engineering roadmap is becoming increasingly important.
Roles include:
- AI Platform Engineer
- AI Infrastructure Engineer
- MLOps Engineer
- Platform Engineer
- GPU Systems Engineer
- AI Reliability Engineer
Demand continues to grow because infrastructure complexity grows alongside AI adoption.
Common Mistakes People Make When Learning AI Infrastructure
The biggest mistake is chasing trends instead of fundamentals.
People spend weeks learning prompt engineering while struggling with Linux basics.
Other common mistakes include:
- Ignoring networking
- Avoiding Kubernetes
- Memorizing tools
- Skipping hands-on projects
- Focusing only on certifications
- Learning AI before learning infrastructure
In my experience, engineers who master fundamentals progress faster than those chasing the newest tools.
Infrastructure rewards depth more than novelty.
A Realistic 6-Month Learning Plan
Month 1
- Linux fundamentals
- Bash scripting
- Networking basics
- Python automation
Month 2
- AWS, Azure, or Google Cloud
- Virtual machines
- Storage
- IAM
- Monitoring
Month 3
- Docker
- Containerization
- Kubernetes fundamentals
- Deploy sample applications
Month 4
- Data pipelines
- Airflow
- MLflow
- CI/CD workflows
- Infrastructure as Code
Month 5
- GPU concepts
- Distributed systems basics
- Model serving
- AI deployment patterns
Month 6
- RAG systems
- Vector databases
- LLMOps workflows
- Platform engineering concepts
Build projects throughout the process.
Projects teach lessons tutorials never will.
Is AI Infrastructure a Good Career Choice?
I believe it is one of the strongest technical career paths available today.
The reason is simple.
Organizations can hire data scientists and ML engineers, but without infrastructure, their models never reach production.
The work is challenging.
You need to understand multiple domains.
You will troubleshoot obscure failures.
You will spend time debugging networking issues that somehow affect GPU workloads.
But the combination of cloud, distributed systems, automation, and AI creates valuable expertise.
The AI infrastructure career path is not the easiest route into technology.
It is, however, one of the most durable.
Infrastructure remains necessary regardless of which AI model dominates next year.
You Might Be Interested In
- What Is Generative Ai? Simple Explanation For Non-tech Readers
- How Do Managed It Services Improve Technology Planning?
- What Are Deepfake Technology Types?
- What Is The Disadvantage Of ChatGPT?
- Guardrails That Dona’t Ruin Ux: Practical Patterns For Refusals And Safe Completions
Conclusion
If someone asks me How Does AI Infrastructure Learning Path Work, my answer is always the same.Start with infrastructure fundamentals.
Learn Linux, networking, Python, cloud platforms, containers, and Kubernetes. Then move into MLOps, GPU systems, LLMOps, and platform engineering.The most effective AI infrastructure roadmap is not built around the latest model release. It is built around understanding how complex systems operate in production.
Do not rush to advanced AI topics.Spend time building a strong foundation.
A surprising amount of AI infrastructure work is still infrastructure work.Once those fundamentals become second nature, the AI-specific layers become far easier to understand and much easier to operate in the real world.
